 |
pulsatrix 1.1.0
|
|
pulsatrix 1.1.0
|
Byte-level pre-tokenization (Hugging Face's ByteLevel): optionally prepends a space, optionally splits with the GPT-2 regex, then maps every byte to a printable character with GPT-2's table, so BPE runs over characters that stand for bytes. More...
#include <byte_level_bpe.hpp>
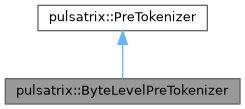
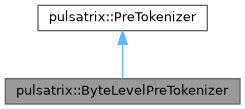
Public Member Functions | |
| ByteLevelPreTokenizer (bool add_prefix_space, bool use_regex) | |
| void | pre_tokenize (std::vector< NormalizedString > &splits) const override |
Replaces splits with their further-split (or transformed) pieces, in order. | |
 Public Member Functions inherited from pulsatrix::PreTokenizer | |
| virtual | ~PreTokenizer ()=default |
Byte-level pre-tokenization (Hugging Face's ByteLevel): optionally prepends a space, optionally splits with the GPT-2 regex, then maps every byte to a printable character with GPT-2's table, so BPE runs over characters that stand for bytes.
| pulsatrix::ByteLevelPreTokenizer::ByteLevelPreTokenizer | ( | bool | add_prefix_space, |
| bool | use_regex | ||
| ) |
|
overridevirtual |
Replaces splits with their further-split (or transformed) pieces, in order.
Implements pulsatrix::PreTokenizer.
 1.9.8