 |
pulsatrix 1.1.0
|
|
pulsatrix 1.1.0
|
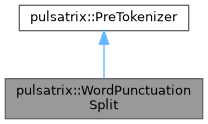
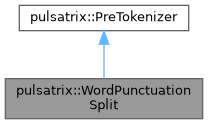
The split Tokenizer::Tokenize makes: runs of ASCII letters, digits and apostrophes are words, ASCII whitespace separates, and every other character is a token of its own. More...
#include <tokenizer_components.hpp>
Public Member Functions | |
| void | pre_tokenize (std::vector< NormalizedString > &splits) const override |
Replaces splits with their further-split (or transformed) pieces, in order. | |
 Public Member Functions inherited from pulsatrix::PreTokenizer | |
| virtual | ~PreTokenizer ()=default |
The split Tokenizer::Tokenize makes: runs of ASCII letters, digits and apostrophes are words, ASCII whitespace separates, and every other character is a token of its own.
|
overridevirtual |
Replaces splits with their further-split (or transformed) pieces, in order.
Implements pulsatrix::PreTokenizer.
 1.9.8