 |
pulsatrix 1.1.0
|
|
pulsatrix 1.1.0
|
Explaining a protein language model residue by residue (PLM-6): AttnLRP from a masked residue's prediction, a mutation's log-odds or a head on the representations back to the input residues, and the checks that keep such explanations honest. More...
#include <cstdint>#include <functional>#include <string>#include <string_view>#include <vector>#include "pulsatrix/attnlrp_parity.hpp"#include "pulsatrix/encoder_lm.hpp"#include "pulsatrix/explainer_capabilities.hpp"#include "pulsatrix/protein_sequences.hpp"#include "pulsatrix/proteingym.hpp"#include "pulsatrix/relevance_graph.hpp"#include "pulsatrix/text_tokenizer.hpp"#include "pulsatrix/variant_scoring.hpp"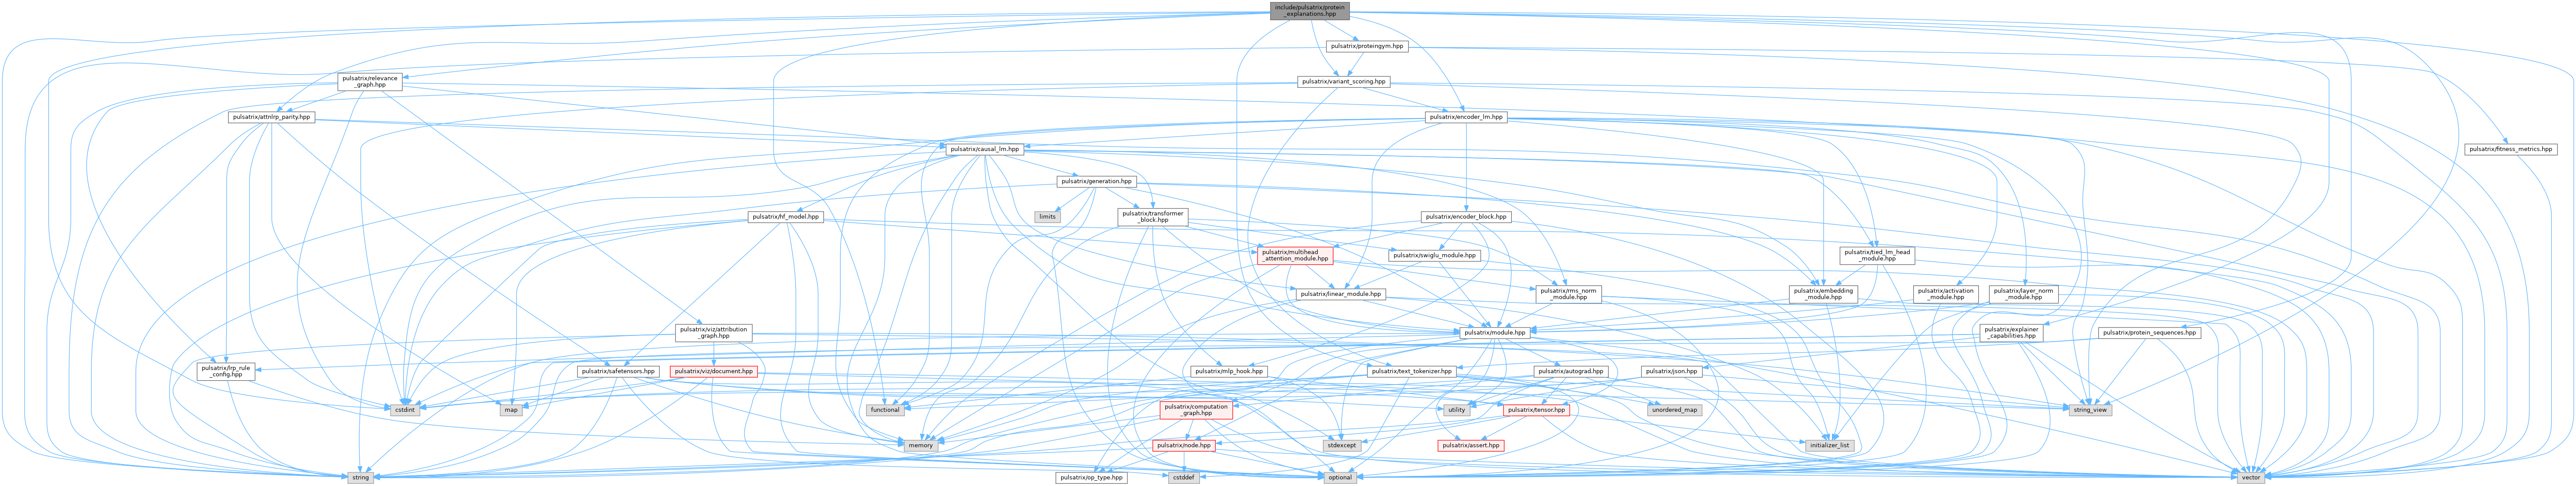
Go to the source code of this file.
Classes | |
| struct | pulsatrix::LinearHead |
A linear head on the model's representations (last_hidden_state): weight . h + bias. More... | |
| struct | pulsatrix::EncoderTarget |
| What an explanation explains. Residues are numbered from 0 here. More... | |
| struct | pulsatrix::ResidueRelevance |
| Relevance per residue for one explained value. More... | |
| class | pulsatrix::EncoderExplainer |
| AttnLRP for an ESM-2 EncoderLM: explains a target (EncoderTarget) as relevance on the input residues, with LXT's rules by default (the identity rule on LayerNorm and GELU, the uniform rule at attention's matmuls, epsilon elsewhere), so it matches LXT's AttnLRP. More... | |
| struct | pulsatrix::ResidueAgreement |
| How a per-residue explanation agrees with an independent per-residue signal. More... | |
| struct | pulsatrix::ResidueDeletionCurve |
| A deletion curve against its random baseline. More... | |
| struct | pulsatrix::RandomizationCheckResult |
The randomization check's result: after randomizing layers[0..i], how similar the explanation stays (Spearman of |relevance| per residue with the original). More... | |
Namespaces | |
| namespace | pulsatrix |
Functions | |
| ResidueAgreement | pulsatrix::CompareResidueSignals (const std::vector< float > &relevance, const std::vector< float > &signal, double top_fraction=0.1) |
Compares |relevance| with signal over the residues where both are finite; top_fraction picks k (at least 1). | |
| std::vector< float > | pulsatrix::DmsPositionSensitivity (const DmsVariants &variants, std::string_view sequence, int64_t offset=1) |
| Each residue's sensitivity in a deep mutational scan: minus the mean score of its single mutants (higher scores being fitter, as in ProteinGym), so residues that tolerate no change rank highest. NaN where no single mutant was measured. Multiple mutants are skipped. | |
| std::vector< float > | pulsatrix::AlignmentConservation (const std::vector< FastaRecord > &alignment) |
Conservation of each query residue in a multiple sequence alignment whose first record is the query: log2(20) - entropy of the column's amino acids, in bits, times the share of sequences without a gap there. NaN for query residues outside the alignment's focus columns (lowercase). | |
| std::string | pulsatrix::AlignmentQuery (const std::vector< FastaRecord > &alignment) |
The query's residues in alignment's first record: its letters, uppercased. | |
| std::vector< float > | pulsatrix::RelevanceProfile (EncoderExplainer &explainer, std::string_view sequence, const std::function< void(int64_t done, int64_t total)> &progress={}) |
| How much the model draws on each residue when it predicts the others: the mean, over every residue's masked wild-type logit (EncoderTarget::MaskedToken), of each residue's share of the explanation's total |relevance|. A per-protein explanation to compare with per-residue signals such as DMS sensitivity or conservation. | |
| ResidueDeletionCurve | pulsatrix::DeletionCheck (EncoderExplainer &explainer, std::string_view sequence, const EncoderTarget &target, const std::vector< float > &relevance, int64_t steps=20, int64_t random_orders=5, uint64_t seed=0) |
Masks residues (<mask>) in order of how much they support the explained value (relevance of the value's own sign, largest first) and records the value, beside random_orders random orders. A faithful explanation moves the value toward zero faster than random. The explained residue itself is never masked twice: a masked target's residue stays masked throughout, and isn't counted. | |
| RandomizationCheckResult | pulsatrix::RandomizationCheck (EncoderExplainer &explainer, std::string_view sequence, const EncoderTarget &target, uint64_t seed=0) |
| Cascading model randomization (Adebayo et al. 2018) over the encoder's own layers, top down: the LM head, then each layer from the last to the first, then the embeddings. Each step redraws the group's weight matrices (Gaussian, each with its own standard deviation) and re-explains. Norm gains and biases are kept: redrawn from their own small spread, a pre-LN block's gains shrink toward zero and the block becomes its residual connection, which would hide the randomization. The model's parameters are restored before returning. | |
Explaining a protein language model residue by residue (PLM-6): AttnLRP from a masked residue's prediction, a mutation's log-odds or a head on the representations back to the input residues, and the checks that keep such explanations honest.
Residue-level explanations can look plausible and still not explain the model: a 2026 study (arXiv 2606.22181) found integrated gradients on a well-performing ESM-2 classifier missed the annotated epitopes. So every explanation here comes with checks against something independent of how it looks:
 1.9.8