 |
pulsatrix 1.1.0
|
|
pulsatrix 1.1.0
|
The tokenizer interface (TOK-1): a pipeline of normalizer, pre-tokenizer, model, post-processor and decoder, as in Hugging Face tokenizers, with added tokens split out first. encode() returns ids, token strings, offsets into the input and a special- token mask; decode() returns text.
More...
#include <cstddef>#include <cstdint>#include <memory>#include <optional>#include <string>#include <string_view>#include <unordered_map>#include <vector>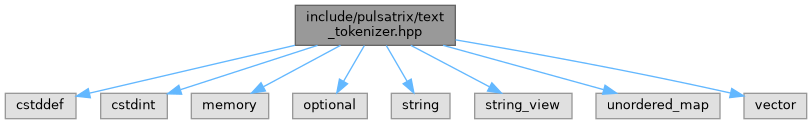
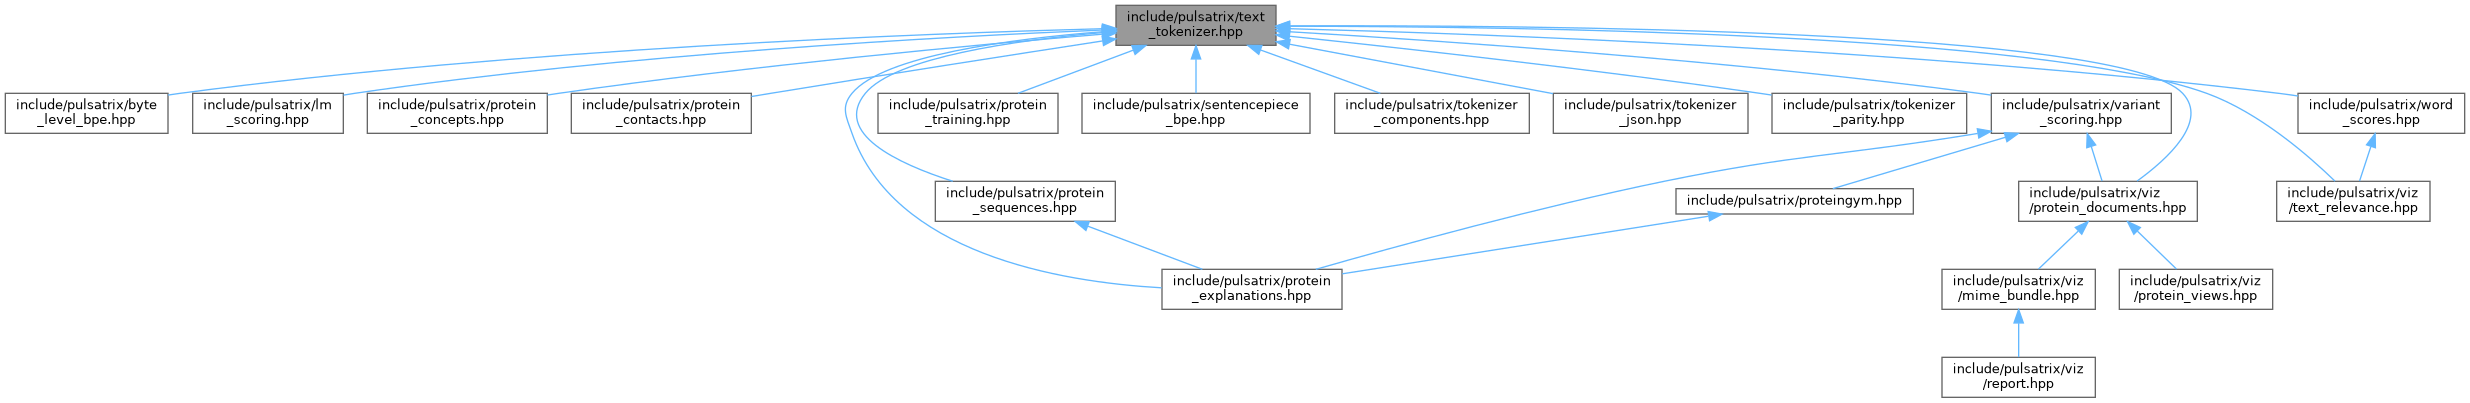
Go to the source code of this file.
Classes | |
| struct | pulsatrix::Offset |
A byte range [begin, end) of the text passed to TextTokenizer::encode(). More... | |
| struct | pulsatrix::Encoding |
| The result of encoding one text. More... | |
| class | pulsatrix::NormalizedString |
| Text being normalized and pre-tokenized, remembering where each byte came from in the original input, so offsets survive changes such as NFC composition or byte-to-character mapping. More... | |
| struct | pulsatrix::NormalizedString::Piece |
| One piece of a rebuilt text: its new bytes, and the range of the current text they replace (an empty range inserts). More... | |
| class | pulsatrix::Normalizer |
| Changes text before it is split (lowercasing, NFC, ...). More... | |
| class | pulsatrix::PreTokenizer |
| Splits text into the pieces the model tokenizes separately, and may change them (byte- level mapping). More... | |
| struct | pulsatrix::ModelToken |
| One token from a TokenModel: its id and string, and the bytes of the piece it covers. More... | |
| class | pulsatrix::TokenModel |
| Turns one pre-tokenized piece into tokens (word-level lookup, BPE, ...). More... | |
| class | pulsatrix::PostProcessor |
| Adds tokens around an encoding (BOS and EOS, sentence pairs, ...). More... | |
| class | pulsatrix::Decoder |
| Turns token strings back into text. More... | |
| struct | pulsatrix::AddedToken |
A token matched in the raw input before anything else runs, such as <|im_start|>. More... | |
| class | pulsatrix::TextTokenizer |
| A tokenizer: added tokens are split out of the raw text first (longest match, earliest first); each remaining segment is normalized, pre-tokenized and tokenized by the model; then the post-processor runs. Every component but the model is optional. More... | |
Namespaces | |
| namespace | pulsatrix |
The tokenizer interface (TOK-1): a pipeline of normalizer, pre-tokenizer, model, post-processor and decoder, as in Hugging Face tokenizers, with added tokens split out first. encode() returns ids, token strings, offsets into the input and a special- token mask; decode() returns text.
 1.9.8