 |
pulsatrix 1.1.0
|
|
pulsatrix 1.1.0
|
Compares a TextTokenizer with Hugging Face tokenizers on a reference corpus (TOK-2), as written by tools/tokenizers/make_tokenizer_reference.py.
More...
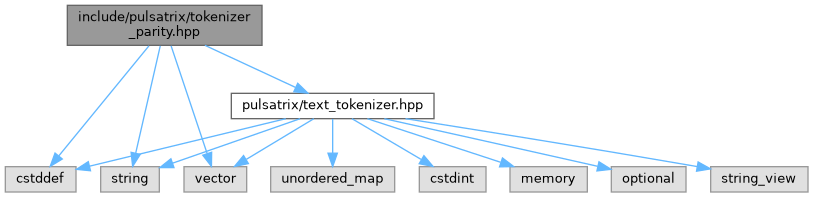
Go to the source code of this file.
Classes | |
| struct | pulsatrix::TokenizerMismatch |
| The first difference on one line of the corpus. More... | |
| struct | pulsatrix::TokenizerParityReport |
| How a tokenizer compares with the reference, field by field. More... | |
Namespaces | |
| namespace | pulsatrix |
Functions | |
| TokenizerParityReport | pulsatrix::CompareToTokenizerReference (const TextTokenizer &tokenizer, const std::string &path, size_t max_examples=5) |
Encodes and decodes every line of a reference file (JSON lines with text, ids, plain_ids, offsets in characters, decoded, decoded_skip, and normalized: whether the normalizer changed the line) and counts the lines that differ. A line round-trips exactly when the normalizer leaves it alone and decoding its plain ids gives it back; offsets are compared exactly on those lines. | |
| Offset | pulsatrix::ByteToCharOffset (std::string_view text, Offset bytes) |
A byte offset range of text as a character (code point) range, widened to whole characters, which is how Hugging Face reports offsets. | |
Compares a TextTokenizer with Hugging Face tokenizers on a reference corpus (TOK-2), as written by tools/tokenizers/make_tokenizer_reference.py.
 1.9.8