 |
pulsatrix 1.1.0
|
|
pulsatrix 1.1.0
|
The components byte-level BPE tokenizers are built from (TOK-2): NFC, regex and digit splitting, byte-level mapping, BPE, template post-processing and byte-level decoding, each following Hugging Face tokenizers.
More...
#include <cstdint>#include <memory>#include <optional>#include <string>#include <unordered_map>#include <utility>#include <vector>#include "pulsatrix/text_tokenizer.hpp"#include "pulsatrix/unicode_regex.hpp"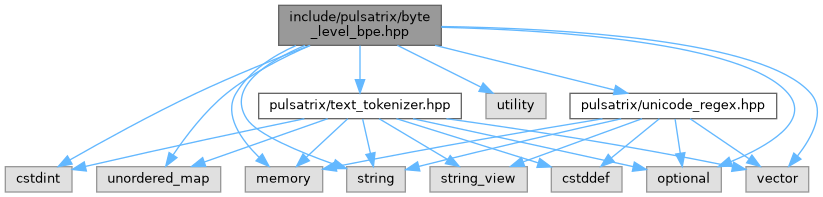
Go to the source code of this file.
Classes | |
| class | pulsatrix::NfcNormalizer |
| Unicode Normalization Form C (canonical composition), keeping offsets. More... | |
| class | pulsatrix::SequenceNormalizer |
| Runs normalizers in order. More... | |
| class | pulsatrix::SplitPreTokenizer |
| Splits on a regex or a literal string (Hugging Face's Split pre-tokenizer). More... | |
| class | pulsatrix::DigitsPreTokenizer |
| Splits off numeric characters (Unicode N), one by one or in runs (Hugging Face's Digits). More... | |
| class | pulsatrix::ByteLevelPreTokenizer |
| Byte-level pre-tokenization (Hugging Face's ByteLevel): optionally prepends a space, optionally splits with the GPT-2 regex, then maps every byte to a printable character with GPT-2's table, so BPE runs over characters that stand for bytes. More... | |
| class | pulsatrix::SequencePreTokenizer |
| Runs pre-tokenizers in order. More... | |
| struct | pulsatrix::BpeOptions |
BPE options beyond the vocabulary and merges, as tokenizer.json names them. More... | |
| class | pulsatrix::BpeModel |
| Byte-pair encoding: start from characters and apply merges, lowest rank first. More... | |
| class | pulsatrix::ByteLevelPostProcessor |
| Byte-level post-processing (Hugging Face's ByteLevel post-processor): with trim_offsets, each token's offsets leave out the spaces at its edges. More... | |
| class | pulsatrix::TemplatePostProcessor |
Special tokens around a single sequence (Hugging Face's TemplateProcessing, single). More... | |
| struct | pulsatrix::TemplatePostProcessor::Item |
One template item: the sequence itself (special empty), or special tokens. More... | |
| class | pulsatrix::SequencePostProcessor |
| Runs post-processors in order. More... | |
| class | pulsatrix::ByteLevelDecoder |
| Maps byte-level characters back to bytes; invalid UTF-8 becomes U+FFFD, as in Hugging Face. More... | |
Namespaces | |
| namespace | pulsatrix |
Enumerations | |
| enum class | pulsatrix::SplitBehavior { pulsatrix::Removed , pulsatrix::Isolated , pulsatrix::MergedWithPrevious , pulsatrix::MergedWithNext , pulsatrix::Contiguous } |
| What a split does with the pieces that match (Hugging Face's SplitDelimiterBehavior). More... | |
Functions | |
| const std::vector< std::string > & | pulsatrix::ByteLevelAlphabet () |
| The GPT-2 byte-to-character table byte-level BPE uses: printable bytes stand for themselves, the rest for U+0100 onward. | |
The components byte-level BPE tokenizers are built from (TOK-2): NFC, regex and digit splitting, byte-level mapping, BPE, template post-processing and byte-level decoding, each following Hugging Face tokenizers.
 1.9.8