 |
pulsatrix 1.1.0
|
|
pulsatrix 1.1.0
|
A soft decision tree (Frosst and Hinton, "Distilling a Neural Network Into a Soft Decision Tree", 2017): an interpretable student for a network teacher (roadmap KD-3). More...
#include <cstdint>#include <utility>#include <vector>#include "pulsatrix/linear_module.hpp"#include "pulsatrix/module.hpp"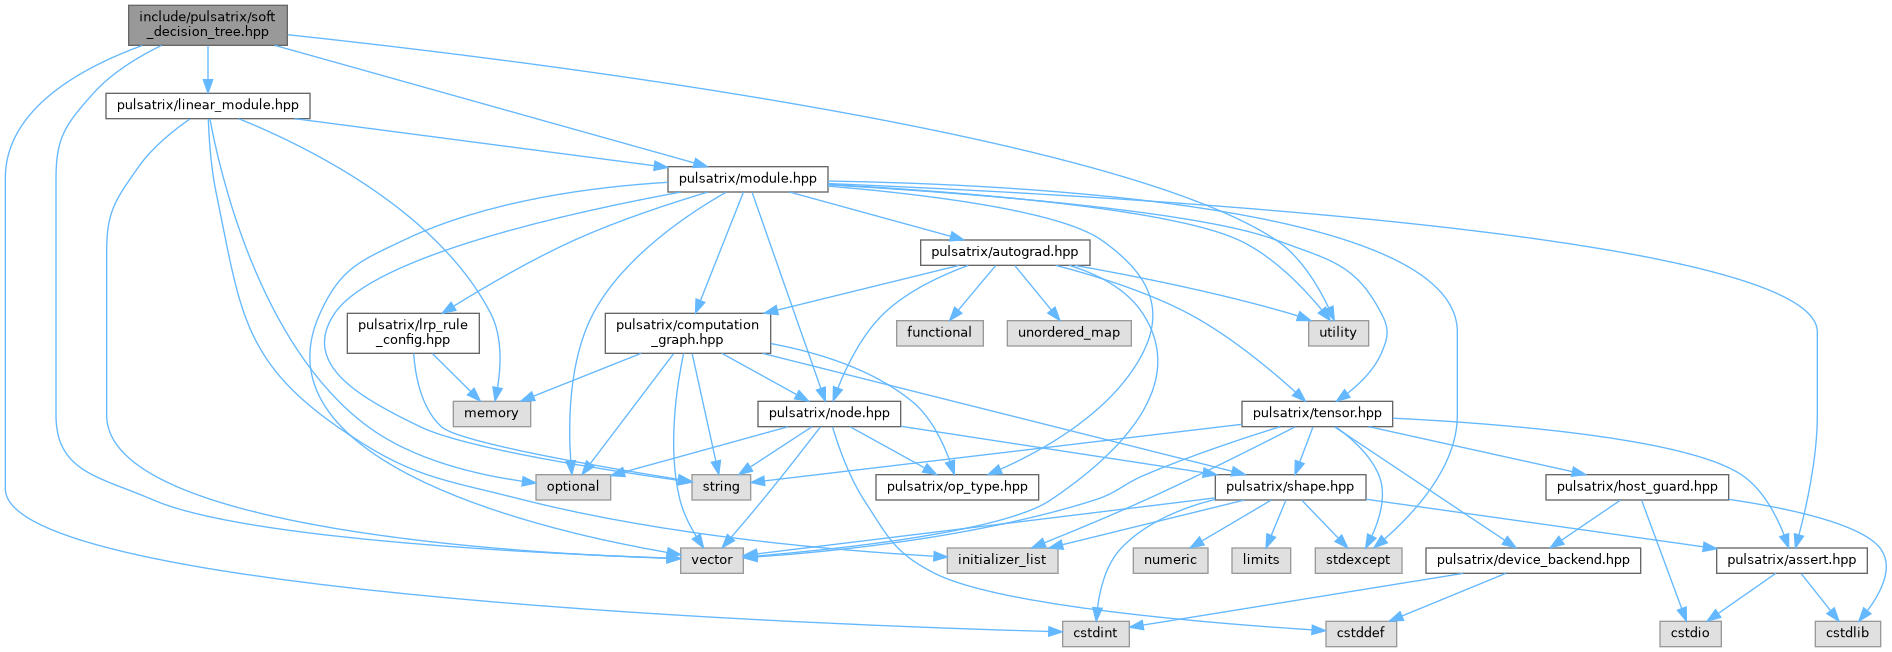
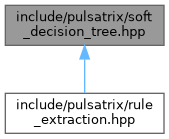
Go to the source code of this file.
Classes | |
| struct | pulsatrix::SoftDecisionTreeOptions |
| SoftDecisionTree's settings. More... | |
| class | pulsatrix::SoftDecisionTree |
| Frosst and Hinton's soft decision tree, (N, inputs) to (N, classes) log-probabilities. More... | |
Namespaces | |
| namespace | pulsatrix |
A soft decision tree (Frosst and Hinton, "Distilling a Neural Network Into a Soft Decision Tree", 2017): an interpretable student for a network teacher (roadmap KD-3).
A complete binary tree of depth d. Inner node i sends an input right with probability p_i(x) = σ(β (x · w_i + b_i)) and left with 1 − p_i(x); each leaf ℓ holds a distribution Q_ℓ = softmax(φ_ℓ) over the classes. An input reaches leaf ℓ with probability P_ℓ(x), the product of the choices on its path, and the tree's output is the mixture
y(x) = log Σ_ℓ P_ℓ(x) Q_ℓ,
log-probabilities, so it trains with DistillationLoss on a teacher's logits (softmax(y) is the mixture itself) or with CrossEntropyLoss on labels. Every decision is one learned linear filter, which can be read directly: Frosst and Hinton show them as images. To explain one prediction, follow the most probable path, MostProbableLeaf(), and read its filters and its leaf.
Frosst and Hinton's penalty keeps every inner node from sending nearly everything one way: with α_i the share of the probability reaching node i that goes right over a batch,
C = −λ Σ_i 2^(−depth(i)) · ½ (log α_i + log(1 − α_i)),
added to the loss when penalty is positive. Unlike the paper, α is the current batch's alone, not a moving average over batches.
Nodes are numbered as a heap: node i's children are 2i + 1 (left) and 2i + 2 (right); the 2^d − 1 inner nodes come first and leaf ℓ is node 2^d − 1 + ℓ.
tests/soft_decision_tree_test.cpp checks the output, the gradients and the penalty against tools/generate_soft_decision_tree_reference_values.py (numpy, gradients by central differences).
 1.9.8