 |
pulsatrix 1.1.0
|
|
pulsatrix 1.1.0
|
Pipeline components for TextTokenizer (TOK-1), and the word-level, byte and character tokenizers built from them. More...
#include <string>#include <unordered_map>#include <vector>#include "pulsatrix/text_tokenizer.hpp"#include "pulsatrix/vocabulary.hpp"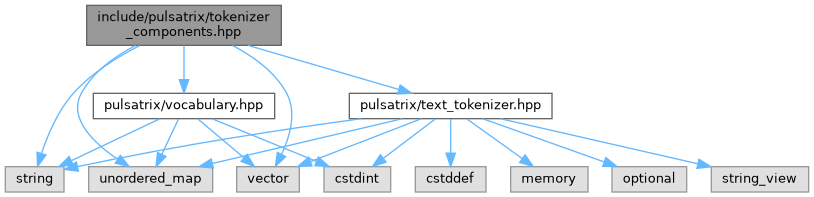
Go to the source code of this file.
Classes | |
| class | pulsatrix::AsciiLowercase |
| Lowercases ASCII letters and leaves every other character alone. More... | |
| class | pulsatrix::WordPunctuationSplit |
| The split Tokenizer::Tokenize makes: runs of ASCII letters, digits and apostrophes are words, ASCII whitespace separates, and every other character is a token of its own. More... | |
| class | pulsatrix::WordLevelModel |
| Each piece is one token, looked up in a vocabulary; unknown pieces become the unknown token. More... | |
| class | pulsatrix::ByteModel |
| Every byte is a token whose id is the byte's value (0..255); the token string is the byte itself. More... | |
| class | pulsatrix::CharModel |
| Every character (code point) is a token, looked up in a character list; unknown characters become the unknown token. More... | |
| class | pulsatrix::FuseDecoder |
| Concatenates the tokens (Hugging Face's Fuse decoder). More... | |
Namespaces | |
| namespace | pulsatrix |
Functions | |
| TextTokenizer | pulsatrix::MakeWordLevelTokenizer (const Vocabulary &vocab) |
The word-level tokenizer over a Vocabulary: AsciiLowercase, WordPunctuationSplit and a WordLevelModel whose unknown token is <unk> (id 0). On ASCII text its tokens are Tokenizer::Tokenize's and its ids are Vocabulary::IndexOf's. | |
| TextTokenizer | pulsatrix::MakeByteTokenizer (const std::vector< std::string > &special_tokens={}) |
Bytes as ids 0..255, then special_tokens as ids 256, 257, ...; decodes by concatenation. | |
| TextTokenizer | pulsatrix::MakeCharTokenizer (std::vector< std::string > chars, const std::vector< std::string > &special_tokens={}) |
Characters by id from chars, then <unk> (unless chars has it), then special_tokens; decodes by concatenation. | |
Pipeline components for TextTokenizer (TOK-1), and the word-level, byte and character tokenizers built from them.
 1.9.8