|
| | FeedForwardModule (int64_t d_model, int64_t d_ff, DeviceBackend *backend, ElementwiseOp activation=ElementwiseOp::Gelu, bool bias=true) |
| |
| Tensor | backward (const Tensor &grad_output) override |
| | Computes the gradient w.r.t. this module's input, given the gradient w.r.t. its output. Must be called after forward() – uses state cached from that call.
|
| |
| Tensor | propagate_relevance (const Tensor &relevance_out, const LRPRuleConfig &config) override |
| | Computes this module's contribution to LRP relevance propagation.
|
| |
| OpType | op_type () const override |
| | A chain of other modules.
|
| |
| std::vector< NamedParamRef > | named_parameters () override |
| | This module's trainable parameters, each with its hierarchical name – the one place a module declares its parameters (roadmap FND-1).
|
| |
| std::vector< NamedModuleRef > | named_children () override |
| | This module's direct sub-modules, each under the prefix its parameters carry in named_parameters(), in the same order (TRN-7: how ApplyLora() finds a model's Linear layers). Default: none. NamedModules() walks the whole tree.
|
| |
| std::vector< NamedBufferRef > | named_buffers () override |
| | This module's buffers: state a checkpoint must save that no optimizer updates.
|
| |
| void | set_training (bool training) override |
| | Sets this module's training/eval mode. Defaults to training (matches every mainstream framework's Module default).
|
| |
| std::optional< DeviceType > | compute_device () const override |
| | The device this module computes on, so forward() can reject an input on another device before any kernel sees it (roadmap FND-8).
|
| |
| LinearModule & | fc1 () |
| |
| ActivationModule & | activation () |
| |
| LinearModule & | fc2 () |
| |
| void | release_activations () override |
| | Frees the tensors forward() kept for backward() and the relevance passes; containers release their children too. Inference that only needs the output calls it after each forward, so a deep model holds one layer's activations at a time (a 1024-token ESM-2 650M pass otherwise keeps over 10 GB of them).
|
| |
| virtual | ~Module ()=default |
| |
| Tensor | forward (const Tensor &input) |
| | Runs this module's forward computation.
|
| |
| std::pair< Tensor, NodeId > | forward_traced (const Tensor &input, NodeId input_node, ComputationGraph &graph, Autograd &autograd) |
| | Runs forward() while also registering a ComputationGraph node (tagged with this module's op_type(), parented to input_node) and wiring an Autograd backward function that reuses this module's own backward() – the opt-in traced/explainable path, per Phase 2 Mission 0.
|
| |
| virtual bool | supports_lrp_rule (LRPRule rule) const |
| | Whether propagate_relevance() implements rule (no silent fallback: callers such as ExplainerContext::relevance_pass() throw rather than run a module on a rule it does not implement).
|
| |
| virtual std::vector< ParamRef > | parameters () |
| | This module's trainable parameters and their gradients, for an optimizer to update uniformly across module types.
|
| |
| void | set_requires_grad (bool requires_grad, const std::string &prefix="") |
| | Freezes (false) or unfreezes (true) parameters by name (roadmap FND-2).
|
| |
| bool | is_training () const |
| | Whether this module is currently in training mode.
|
| |
fc2(f(fc1(x))) over the last dimension. Shape (..., d_model) -> (..., d_model).
- Note
- Parameters are named
fc1.* and fc2.*. LRP: each Linear's own rule (the config's), relevance passed through the activation unchanged.

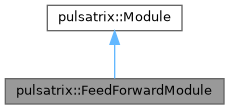
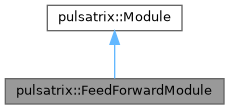
 Public Member Functions inherited from pulsatrix::Module
 1.9.8